MINT
Multidimensional Interoceptive Traits questionnaire · Makowski et al.
How people sense the inside of their own body, as a trait.
The
The Science-based Assessment of Deep Personality
Research-grade measures · immediate results · entirely anonymous
Documentation
Psychology runs on questionnaires, and nearly all of them are asked the same way: a page of radio buttons on a platform built for the person writing the study, not the person answering it.
The instruments are rarely what fails; the answering is. No amount of validation survives careless answers, and a dataset nobody can trust is not one worth sharing.
Qualtrics, Gorilla, jsPsych and the rest are good at building a study and indifferent to taking one: grid after grid, a progress bar at best, a thank-you at the end. Nothing in them is designed to be finished.
Attention falls with length. The same item is answered worse at the end of a long battery than at its start, and the people who stop halfway are not a random half.
Straight lines, the middle of every scale, a second an item: often a tenth of an online sample or more (Meade & Craig, 2012), in panels that pay by the minute and reward the quick. It is not only noise: it can make unrelated scales correlate (Huang et al., 2015).
An hour of honest answers buys a debriefing sheet. The participant learns nothing about themselves, so there is no reason to care how they answer, to come back or to tell anybody else.
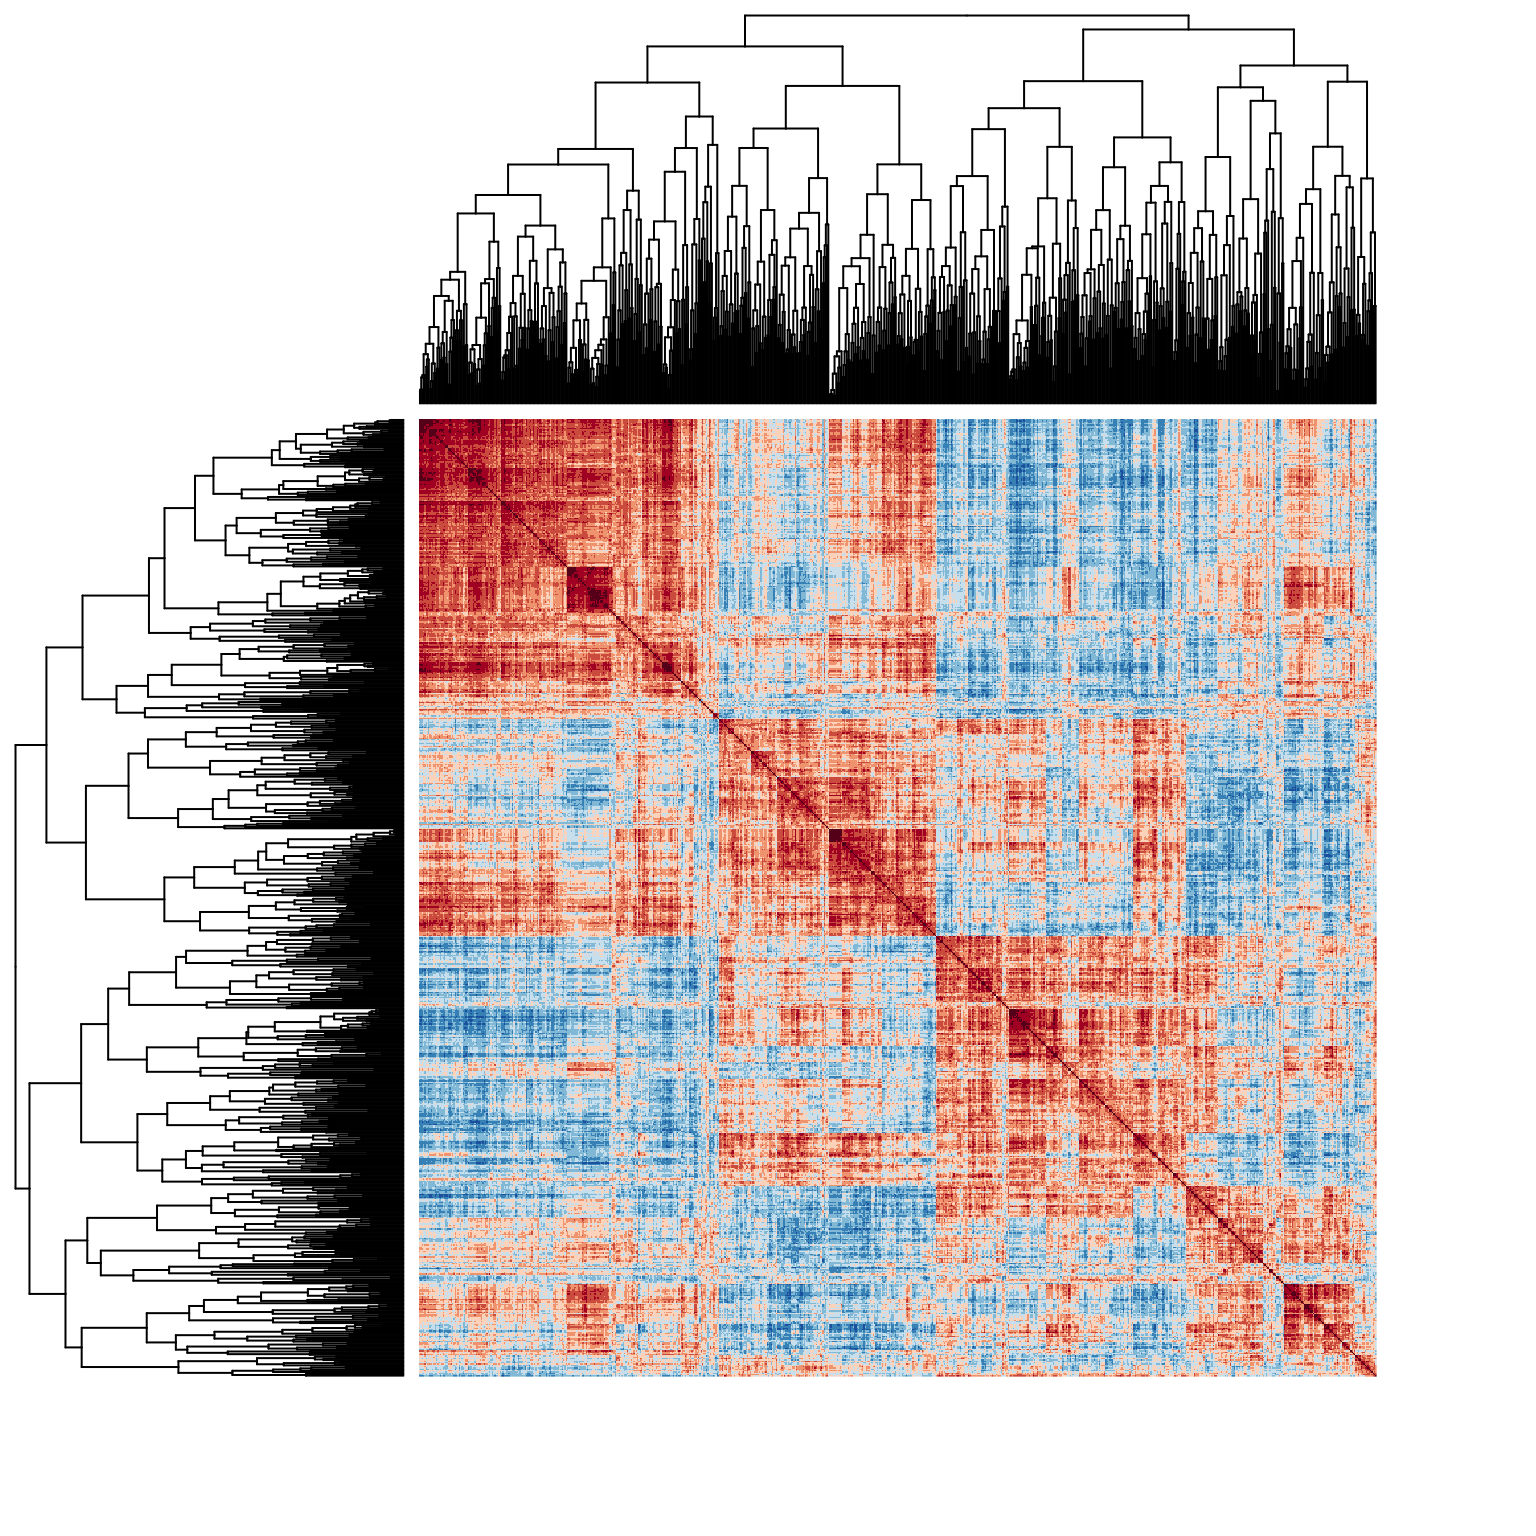
One name for different things, different names for one thing. Scales multiply (most are used once or twice; Elson et al., 2023) and are seldom asked side by side, so how far grit is conscientiousness, or worry rumination, is rarely checked in one sample.
Each study asks a handful of scales of a few hundred people and keeps the file. Pooling them afterwards means reconciling versions, formats and samples that were never meant to meet.
A survey platform built to be engaging enough that people want to finish it. The questionnaires underneath are ordinary validated ones, asked as they were written; everything around them is there to keep somebody reading the question they are answering, to the last of them.
The aim is high-quality, re-usable, open-access datasets, clean enough to be pooled and wide enough to show how far their measures overlap, since the same people answer all of them.
The run is levels, dressed as a dive: a gauge in metres, landmarks passed on the way down, the seabed and the rock beneath it. What is left is always in sight and the next stretch always short.
Every level closes on a figure drawn from the answers just given (a body, a hill, a sea, a wheel) rather than a score. It is what is worth reaching, and why the next level gets answered.
After the first level, participants choose which part of themselves to test next, from two or three cards at a time. The order is drawn, then theirs; carrying on is their decision.
Each level finished mints a badge onto a shelf, and a whole-run profile fills in as the levels do. The run accumulates something to look at, not just a bar filling up.
Every reading can be agreed or disagreed with and every level rated. The verdict is data too, including on a star sign read beside a temperament: the Barnum effect caught in the act.
A level's results or the whole profile go out as a link or an image, which opens into the test for whoever receives it: recruitment by word of mouth, filed as such.
Answers are saved as they are given, and a run left partway is picked up where it stopped on the same device, so closing the tab costs neither the participant nor the data.
Attention checks, response times and a closing question on whether it was taken seriously are recorded for every level, and shown to nobody.
Built to be changed: the questions are data rather than code, and a study asks its own battery from its own link.
Multidimensional Interoceptive Traits questionnaire · Makowski et al.
How people sense the inside of their own body, as a trait.
Beliefs about Artificial Intelligence Technology · Makowski et al.
What people believe AI can make, and how they feel about it.
Core · levels 1–4, every participant
Optional · levels 5–10, the participant's choice
Multidimensional Interoceptive Traits questionnaire · Makowski et al.
Its first validation (ER/MB2021/2, two studies) established its structure and how it relates to other interoceptive scales. With the two later studies that asked it too, 1,684 people are its norms.
I can notice even very subtle changes in my breathing
Beliefs about Artificial Intelligence Technology · Makowski et al.
As a trait measure that could partly modulate and mediate the anti-AI bias the lab measures in its tasks, drawing on two things:
Current AI algorithms can generate very realistic videos
Much of society will benefit from a future full of AI
partly modulates and mediates
Its psychometric properties have not been ideal, and more work is needed to make it a better measure.
| Level | Questionnaire | Dimensions | Items |
|---|---|---|---|
| 1 | Demographics | None | 6 |
| 1 | Five-Item Personality Inventory (FIPI; Gosling et al., 2003) | Extraversion, Agreeableness, Conscientiousness, Emotional Stability, Openness | 5 |
| 1 | Single Item Narcissism Scale (SINS; Konrath et al., 2014) | None | 1 |
| 1 | Single-Item Self-Rated Health (SRH; DeSalvo et al., 2006) | General Health | 1 |
| 1 | Single-Item Measure of Stress Symptoms (SIMS; Elo et al., 2003) | None | 1 |
| 1 | Single-Item Self-Esteem Scale (SISE; Robins et al., 2001) | None | 1 |
| 1 | Self-Concept Clarity Scale, item 11 (SCCS; Campbell et al., 1996) | None | 1 |
| 1 | Meaning in Life Questionnaire, item 8 (MLQ; Steger et al., 2006) | None | 1 |
| 1 | General Self-Efficacy Single-Item (GSE-SI; Di et al., 2023) | None | 1 |
| 1 | Aesthetic seeking | None | 1 |
| 1 | Single-Item Life Satisfaction Scale (SILS; Cheung & Lucas, 2014) | Life Satisfaction | 1 |
| 1 | Self-placement items | None | 2 |
| 2 | Demographics | None | 9 |
| 2 | Multidimensional Interoceptive Traits questionnaire (MINT; Makowski et al.) | Bodily Awareness, Bodily Clarity, Bodily Sensitivity | 34 |
| 3 | Subjective financial well-being (ESS / OECD item) | None | 1 |
| 3 | MacArthur Scale of Subjective Social Status (Adler et al., 2000) | None | 1 |
| 3 | Beliefs about Artificial Intelligence Technology (BAIT; Makowski et al.) | AI Realism, AI Apprehension, AI Enthusiasm | 27 |
| 4 | Patient Health Questionnaire-4, refined 5-option version (PHQ-4; Kroenke et al., 2009; Makowski et al., 2025) | Anxiety, Depression | 4 |
| 4 | Single-Item Sleep Quality Scale (SQS; Snyder et al., 2018) | Sleep | 1 |
| 4 | Psychiatric history | None | 2 |
| 4 | HiTOP Brief Report (HiTOP-BR; Simms et al., 2026) | Dominance, Unusual Experiences, Bodily Complaints, Solitude, Emotional Intensity, Impulsivity | 46 |
| 5 | HEX-ACO-18 (Olaru & Jankowsky, 2022) | Honesty-Humility, Emotionality, Sociability, Patience, Diligence, Curiosity | 19 |
| 5 | Social Desirability-Gamma Short Scale (KSE-G; Kemper et al., 2014) | None | 6 |
| 6 | Open Source Archetype Indicator – Pearson-Marr (OSAI-PM) | Idealist, Sage, Seeker, Revolutionary, Magician, Warrior, Realist, Jester, Lover, Creator, Ruler, Caregiver | 37 |
| 7 | Primals Inventory-18 (PI-18; Clifton & Yaden, 2021) + five tertiary scales (PI-99; Clifton et al., 2019) | Enticing, Alive, Safe, Acceptable, Changing, Hierarchical, Interconnected, Understandable | 41 |
| 8 | ICAR-16 Sample Test (ICAR16; Condon & Revelle, 2014; Young & Keith, 2020) | Verbal, Logical, Visual, Spatial | 16 |
| 9 | Adult ADHD Self-Report Scale v1.1, items 1-2 (ASRS; Kessler et al., 2005) | Inattention | 2 |
| 9 | Cognitive Failures Questionnaire, items 10 and 21 (CFQ; Broadbent et al., 1982) | Absent-Mindedness | 2 |
| 9 | Mind Wandering: Spontaneous, items 1 and 4 (MW-S; Carriere et al., 2013) | Mind Wandering | 2 |
| 9 | Brief Self-Control Scale, items 1-2 (BSCS; Tangney et al., 2004) | Self-Control | 2 |
| 9 | Emotion Reactivity Scale, six items (ERS; Nock et al., 2008) | Emotional Sensitivity, Emotional Arousal, Emotional Persistence | 6 |
| 9 | Cognitive Emotion Regulation Questionnaire, short form (CERQ-short; Garnefski & Kraaij, 2006) | Self-Blame, Acceptance, Rumination, Positive Refocusing, Refocus on Planning, Positive Reappraisal, Putting into Perspective, Catastrophising, Other-Blame | 19 |
| 10 | Left-right self-placement (European Social Survey) | None | 1 |
| 10 | Conspiracy Mentality Questionnaire, items 1, 4 and 5 (CMQ; Bruder et al., 2013) | Suspicion | 3 |
| 10 | British Social Attitudes left-right and libertarian-authoritarian scales, adapted (BSA; Evans et al., 1996) | Sharing, Order | 7 |
| 10 | Equality of outcomes between groups | Parity | 5 |
| 10 | Human enhancement and heredity beliefs | Enhancement, Heredity | 7 |
| 10 | Climate, animals and the environment | Planet, Animals | 9 |
| 10 | Beauty against purpose | Beauty | 3 |
| 10 | Words Can Harm Scale, items 6 and 8 and one reversed item, adapted (WCHS; Pratt et al., 2026) | Words | 3 |
| 5 | Interim items, at the end of the core | None | 2 |
| 11 | Closing items | None | 2 |
Hierarchical Taxonomy of Psychopathology · Kotov et al., 2017
A classification of mental ill health built from how symptoms go together rather than from diagnostic categories. Problems sit on spectra that everybody falls somewhere along, arranged in a hierarchy from one general factor down to single symptoms.
The HiTOP-BR (Brief Report; Simms et al., 2026): 45 statements about the last twelve months, on four points from "Not at all" to "A lot", none reversed, scored as the mean of each of six spectra. Its norms are the development sample's (N = 780), through the {hitop} R package, which also scores a saved file directly.
General factor (p) 12 items across the spectra
Externalizing 10 items
My moods were intense and unpredictable
I felt something was wrong with my body
My fantasies felt very real to me
I was happiest when I was alone
I had trouble planning and keeping to schedules
I deserved special treatment
The two scales over the spectra are scored at analysis time.
What piloting the test should send back, and at what grain: excerpts of three pilots' notes on an earlier version, all addressed since.
Pilot 1Line by line: wording, punctuation, layout
Pilot 2Level by level, with how long each took
Pilot 3On a phone and a laptop
PositivesWhat worked, so that it is kept
Very cool user experience - definitely engaging!
I liked the hill metaphor and the overall use of images throughout the test to help understand and visualise the
results
Compared to a normal test, it actually made me want to keep going and see what the next level was
NegativesWhat confused, broke or got in the way
For PHQ-4 section, the visual format of the question items is different to that in previous sections (although,
may be intentional)
I get through hard times by finding what is funny in them.
… what or who is them
? No text above
the question either.
Sometimes when I tried to tap on a specific number, it wouldn’t select the number I was actually pressing … I
tried to select 40 but it would sometimes go to 47
Things to fixWhere it is, what it says, what it should say
contains
→ contain
on first paragraph lineNow, how have you been lately.
requires a question mark rather than a full stop
maybe add PMDD in the
what are you diagnosed with
question especially if you're tracking mood
the
Disagree
and Agree
labels were in the middle of the scale, underneath around 2 and 4, rather
than at the ends underneath 0 and 6
Subjective reactionsHow it felt: the effort, the time, whether it rang true
On the glosses in brackets: I feel it comes across as a bit overwhelming
This level was a little hard so I didn't put lots of effort to answer the questions properly towards the
end
I think it looks a bit nicer on the laptop, but it was still really good on the phone
Say which device and browser, name the level, and quote the words on screen: a note that can be found is a note that can be fixed.
For next week